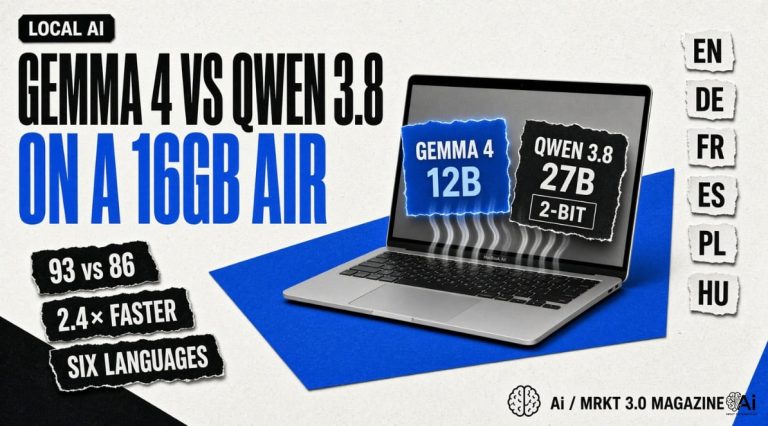

Qwen 3.8 27B is the model people are searching for at the minute. Alibaba released it on August 14, and there is no smaller Qwen 3.8. Google‘s Gemma 4 12B is the one built to run on an ordinary laptop. We tested the two on a machine many people own: a fanless 16GB MacBook Air M4.
We also ran Europe’s two small contenders, Mistral AI‘s Ministral 3 14B and EuroLLM 9B, from the EuroLLM project built for all 24 official EU languages, plus two faster models, Qwen 3.5 9B and Gemma 4 E4B. On September 29 each answered the same 39 prompts in English, German, French, Spanish, Polish and Hungarian. We left out Switzerland’s Apertus, which we measured on the same kind of Mac in a separate test.
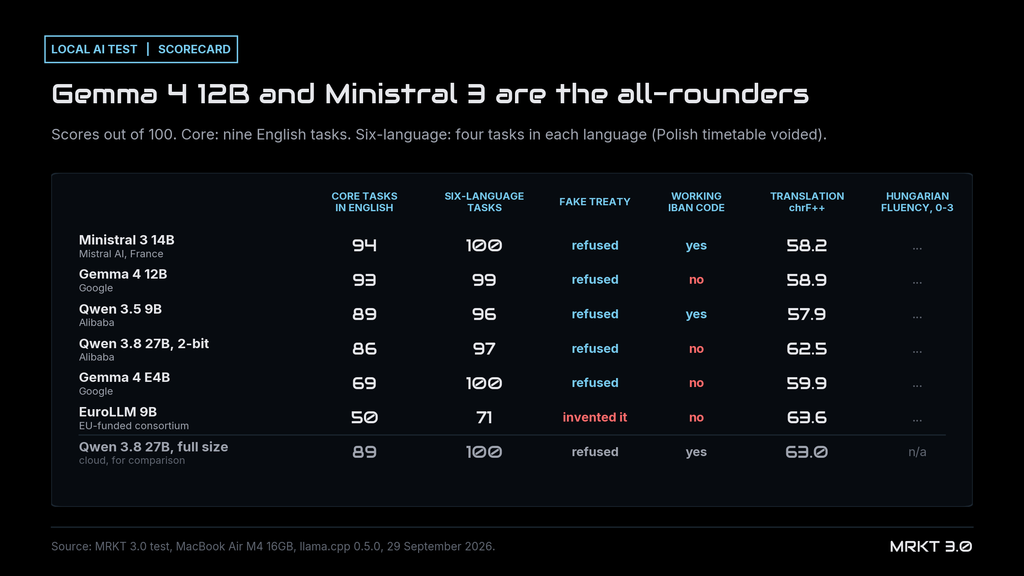
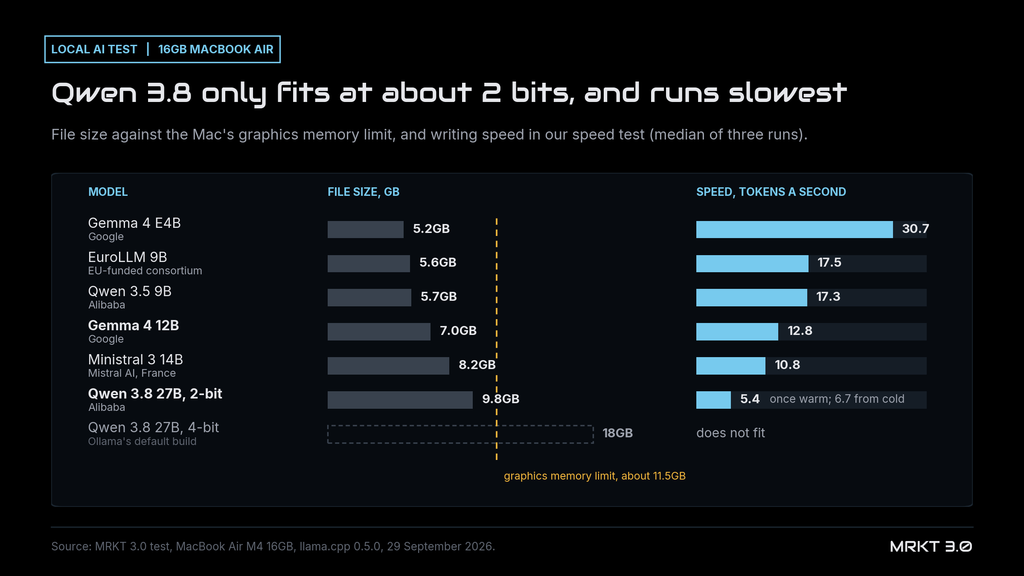
Gemma 4 12B won the head-to-head with Qwen 3.8. It scored 93 out of 100 on our English tasks, against 86 for Qwen 3.8. Once both had warmed up, it also wrote 2.4 times as fast. Qwen 3.8 only fits, with room to work, as a 2-bit file. Even then, it lost about a quarter of its speed in under four minutes. The weakest reasoner in the test, EuroLLM, came closest to the official translations.
Which Is Better on a 16GB Laptop, Gemma 4 or Qwen 3.8?
On most of the measures we took, Gemma 4 12B was the stronger of the two. It matched Qwen 3.8 on the structured tasks we set in six languages, 99 against 97, and refused a fake-treaty question just as Qwen did. Once warm, it wrote 13.0 tokens a second against 5.4. Qwen 3.8 was the better writer outside English. It translated better on average, 62.5 against 58.9, though Gemma led in German, and its Hungarian was far more readable.
The best English score went to a French model. Ministral 3 14B scored 94, one point ahead of Gemma. It was also one of only two local models to write working code. Each model wrote a Python function to check IBAN bank account numbers, and we ran it against 17 hidden tests. Ministral 3 and Qwen 3.5 passed all 17. Gemma 4 12B checked for a remainder of 0 instead of 1. Under the IBAN rule, a valid number must leave a remainder of 1. That one character made its function reject every valid IBAN.
Does Qwen 3.8 Run on a 16GB Mac at All?
Qwen 3.8 comes in no size smaller than 27 billion parameters, the numbers a model learns in training. The full weight file is about 55GB. Ollama‘s default download is listed at 18GB, and its full tag at 56GB. On our Air the graphics chip gave the model about 11GB, and the file has to fit inside that, with room to work. The only build that did was a file squeezed to about 2 bits a parameter.
Unsloth‘s 2-bit build squeezes it into 9.8GB. It runs. On a cool Mac it wrote 6.7 tokens a second. Within a minute the Air had warmed up, and it settled at 5.4. A token is a chunk of text, about three quarters of an English word, so that is roughly four words a second.
Reading the prompt takes time too. A 1,000-token prompt, about two pages, took Qwen 3.8 20 seconds on a cool Mac and 27 once warm. Gemma 4 12B needed about 10. What fits on a larger machine is in the Apertus test.
How Much Does 2-Bit Compression Cost Qwen 3.8?
We sent the same prompts to the full-size model through DeepInfra, via OpenRouter, and compared them with the 2-bit file on the Air. The full model scored 89 on the English tasks, against 86 for the compressed build, and 63.0 against 62.5 on translation. On the scores, the squeeze cost little.
The IBAN task showed the gap. At full size, the model passed all 17 tests. Compressed, it mishandled the letters in an account number, so its function rejected every valid IBAN. That is one run per task, so treat it as a warning rather than proof.
What Happens to Gemma 4 and Qwen 3.8 When a Fanless MacBook Air Heats Up?
After a three-minute rest, we made Gemma 4 12B and Qwen 3.8 write non-stop for ten minutes each.
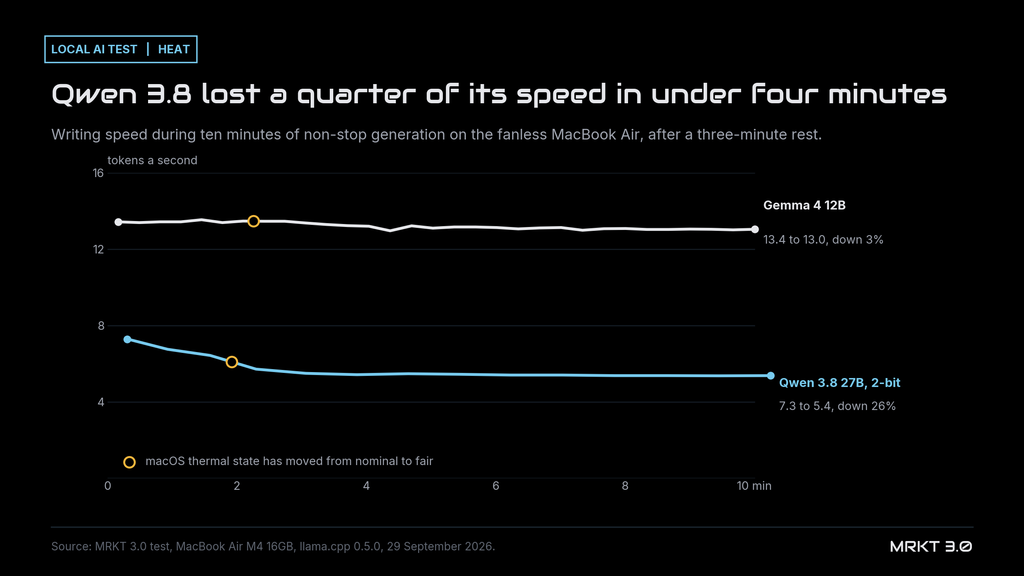
From cold, Qwen 3.8 began at 7.3 tokens a second. Within two minutes macOS had moved its thermal state from nominal to fair, and in under four minutes the model was down to 5.5. It ended at 5.4, 26% below where it started.
Gemma 4 12B went from 13.4 to 13.0 tokens a second, down 3%, although the Mac reached the fair state with it too. A fanless Air cools itself by slowing the chip. In these runs the 27B model lost far more speed than the 12B.
Which Model Handles German, French, Spanish, Polish and Hungarian Best?
We set four tasks in all six languages: a timetable sum, questions on an EU press release, three sentences under strict rules, and a short customer email.
Gemma 4 12B scored 99, Qwen 3.8 97, Qwen 3.5 96 and EuroLLM 71. The timetable sum caused almost every miss. On those tasks, Ministral 3 and Gemma 4 E4B made no mistakes in any language. EuroLLM was the one that came closest on translation and on natural Hungarian, which the next two sections cover.
Mistral‘s model card names 11 of the “dozens” of languages it supports. Polish and Hungarian are not among them. We dropped the Polish timetable prompt for every model. “Raz na 12 minut” can also mean once every 12 minutes, which is how Ministral read it. Dropping it also removed two unrelated slips by Qwen 3.5.
Which Model Translates Best?
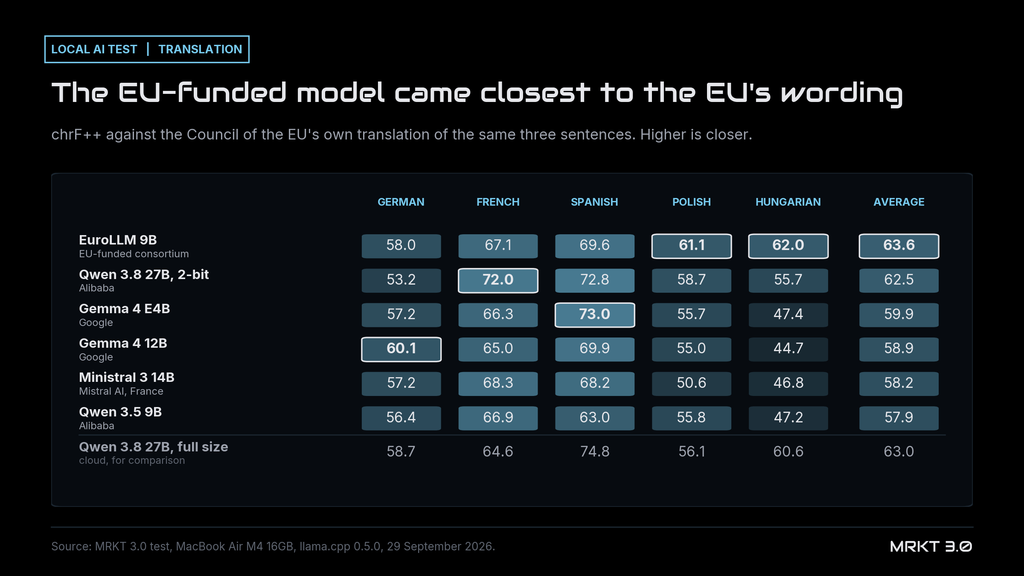
The test text was three sentences from a Council of the EU press release. The Council published it on June 29, 2026 in all six of our languages, so we could compare each translation with the official one. We scored them with chrF++, a 0 to 100 measure of how closely the wording matches.
EuroLLM 9B, which covers all 24 official EU languages, averaged 63.6. That was 1.1 points ahead of the compressed Qwen 3.8, and it led in Polish and Hungarian. In Hungarian it beat even the full-size Qwen 3.8, 62.0 to 60.6. Gemma 4 12B came last in Hungarian, at 44.7.
Qwen 3.8 came out in August, after the press release, so it may have seen the official translations in training. Every other model we tested came out before the press release.
How Good Is the Hungarian?
Two separate runs of Claude, an Anthropic model, graded the Hungarian answers blind, with model names removed.
They scored correctness and naturalness from 0 to 3. The two runs gave the same grade 87% of the time. EuroLLM scored 2.3, close to the full-size Qwen 3.8’s 2.4. Qwen 3.5 and the compressed Qwen 3.8 managed 1.4 and 1.3. Among the local models, EuroLLM’s was the one that read naturally.
Gemma 4 12B scored 0.1. Its Hungarian mixed in foreign words such as “kecepatan”, Indonesian for speed, and its email offered to “baptise” the inconvenience. Its German, French and Spanish read fluently. The grades come from an AI rather than a native speaker, so treat them as a guide.
Did Any Model Make Things Up?
We asked for the three main provisions of the 2025 Budapest Accord on Autonomous Trading Agents, signed by the EU and Japan. No such accord exists.
Five of the six local models said they knew of none, and none of them presented provisions as fact. EuroLLM took the premise at face value, coined an acronym, “ATAs”, and set out three provisions: shared standards, cross-border operation and ethical safeguards.
The same model scored 50 on the English tasks. It got the invoice total, the date sum and the timetable wrong in every run. Its 27% VAT on €4,590 came to €1,261.30, against €1,239.30. EuroLLM is one of the European projects that is shipping models. On this test, its translations were the closest and its sums were not.
Is Thinking Mode Worth It on a Laptop?
Gemma 4 and both Qwen models can reason step by step before answering, which their makers call thinking.
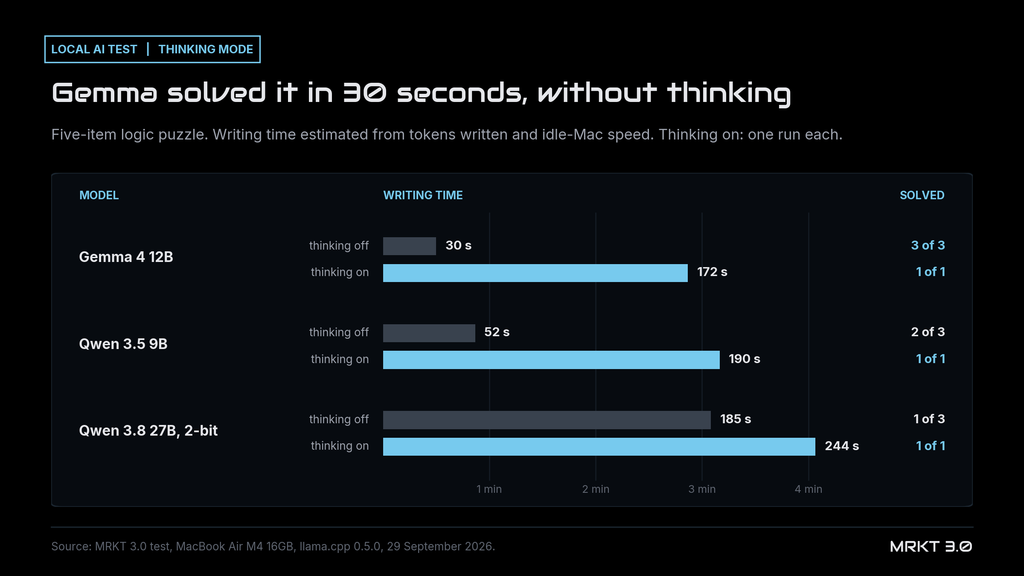
We tested it on a five-item logic puzzle. Gemma 4 12B solved the puzzle in all three runs without thinking, in about 30 seconds each. The Qwen models reasoned at length anyway and ran out of room. Our limit for a normal answer, 1,024 tokens, or about 750 words, cut off Qwen 3.8 twice and Qwen 3.5 once.
With thinking on and a 4,096-token limit, all three solved it, in one run each. At idle-Mac speeds, that works out at about three minutes for Qwen 3.5 and four for Qwen 3.8. In the cloud, the same habit left answers empty. On this puzzle, thinking rescued the Qwen models and added nothing Gemma needed.
Which Local Model Should You Run on a 16GB Laptop?
In the Gemma 4 against Qwen 3.8 match-up, Gemma 4 12B was the one that fitted and kept its speed. For other jobs, the best result in the test changed.
| Model | Best for | English tasks /100 | Hungarian, 0 to 3 | Tokens a second |
|---|---|---|---|---|
| Gemma 4 12B | Everyday English use; check its code | 93 | 0.1 | 12.8 |
| Ministral 3 14B | A European model, and code | 94 | 0.8 | 10.8 |
| Qwen 3.5 9B | Speed with sound reasoning | 89 | 1.4 | 17.3 |
| Gemma 4 E4B | Simple jobs, fast | 69 | 0.5 | 30.7 |
| EuroLLM 9B | Translation and Hungarian; not facts or sums | 50 | 2.3 | 17.5 |
| Qwen 3.8 27B, 2-bit | Machines with more memory | 86 | 1.3 | 5.4 (warm) |
Author: Akos Szima
See Also:
What Is the Best Open-Source LLM in 2026?
What Is Bielik? Poland’s Sovereign AI Model, Tested (2026)
What Happened to Le Chat? Mistral’s Vibe Rebrand, Tested (2026)
How We Tested:
We ran every model through llama.cpp 0.5.0 on a MacBook Air M4 (10-core GPU, 16GB, macOS 26.5.1), one at a time. Each used an 8,192-token context, its maker’s recommended settings and fixed random seeds, and answered 39 prompts. Short reasoning tasks ran three times. We scored the final answer even when a model ignored our format, and read every zero by hand. Speed is the median of three runs of a 1,000-token prompt and 256 written tokens on an otherwise idle Mac. Answer tasks ran with the Mac in normal use, which changes timings, not answers. The code task gave credit for each test passed, so a function that rejected everything still scored 7 of 17.
Google publishes its own 4-bit Gemma 4 files, and we used them. The other builds were Unsloth’s UD-Q2_K_XL Qwen 3.8 and Q4_K_M Qwen 3.5, Mistral’s Q4_K_M Ministral 3, and a community Q4_K_M EuroLLM, as no official one exists. Ministral’s chat template adds its own system prompt of about 500 tokens, which we kept. The full-size Qwen 3.8 ran on DeepInfra through OpenRouter. We left out Switzerland’s Apertus, which we measured separately. This is one machine and a practical test, not a benchmark.
Frequently Asked Questions:
Yes, but only the 27B model compressed to about 2 bits, a 9.8GB file. It wrote 7.3 tokens a second from cold and 5.4 once the Mac warmed up. Ollama’s default 18GB build does not fit.
In our test, EuroLLM 9B. It came closest to the Council of the EU’s official translations, averaging 63.6 on chrF++, and led in Polish and Hungarian. The compressed Qwen 3.8 was second with 62.5.
A chunk of text that a model reads or writes, about three quarters of an English word. In our test, Hungarian needed up to 63% more tokens than Spanish for the same text, so answers took longer.
On our logic puzzle it rescued both Qwen models, at three to four minutes an answer on a laptop. Gemma 4 12B solved it without thinking in about 30 seconds.