
Most rankings of the best open-source LLM answer a question almost nobody is asking, which is: what scores highest? The model that scores highest is Chinese, it has 675 billion parameters, and you cannot run it on anything you own.
The question worth answering is which model you can legally deploy and physically load, and that has a different answer depending on what you are doing with it. Here is the short version.
| Best on capability | Kimi K3, from Moonshot in China. 60 on the Artificial Analysis index. |
| Best you can actually sign | Mistral Small 4. Apache 2.0, 119B total and 6.5B active, 256k context. |
| Best on one machine | Devstral Small 2 24B for code, Apertus v1.5-8B for everything else. |
| Do not pick | Teuken-7B, non-commercial. Five more ship under a US company’s licence. |
| Read this first | A European company cannot license Llama 4’s multimodal models at all. |
Which Open-Source LLM Scores Highest?
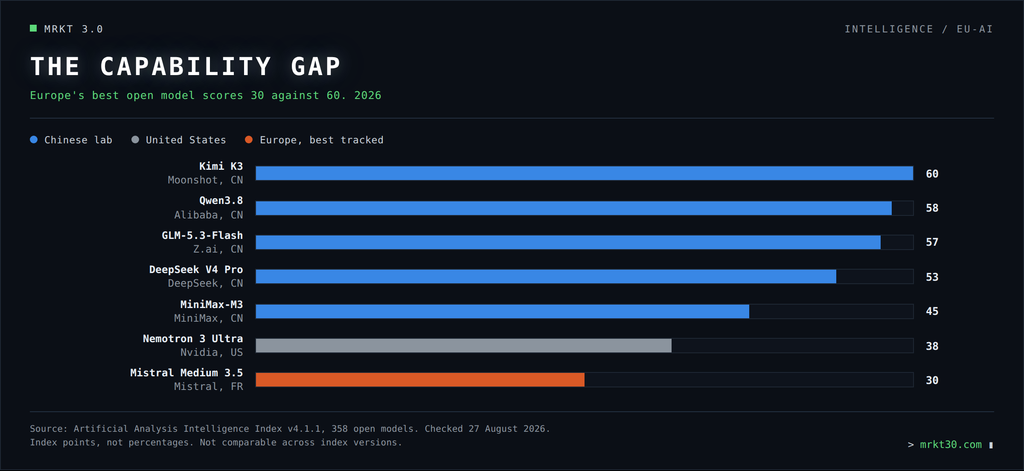
Artificial Analysis tracks 358 open models. Its v4.1.1 index puts Moonshot’s Kimi K3 at 60, Alibaba’s Qwen3.8 at 58, Z.ai’s GLM-5.3-Flash at 57 and DeepSeek V4 Pro at 53. The first non-Chinese entry is Nvidia’s Nemotron 3 Ultra at 38. The first European one is Mistral Medium 3.5 at 30, and it is not Apache 2.0.
If a benchmark number is the only thing that matters to you, download Kimi K3 and stop reading. Most people cannot, for two reasons that have nothing to do with quality. The licence will not let them, or the hardware will not hold it. Both are below.
The Best Open-Source LLM for Each Job
There is no single best model, and any ranking that names one is answering the wrong question. There is a best one for each job. The licence column decides more of these rows than the benchmark column does.
| If you are doing this | Use this | Licence | Why |
|---|---|---|---|
| General work, one model for everything | Mistral Small 4 (119B total, 6.5B active, 256k) | Apache 2.0 | The best combination in Europe of permissive terms, current training and a context window long enough for real documents |
| Coding | Devstral Small 2 24B | Apache 2.0 | 68.0% on SWE-Bench Verified, and it fits on hardware a small team already owns |
| All 24 EU languages | EuroLLM-22B-Instruct-2512 | Apache 2.0 | 35 languages, built by a six-university consortium on EuroHPC. The 32,768 context is the catch |
| Running on your own machine | Apertus v1.5-8B | Apache 2.0, acceptable-use gate | 262,144 context and published training data, but read the tooling warning below before you commit |
| One European language, self-hosted | Bielik 11B v3.0 | Apache 2.0 | Polish-optimised, volunteer-built, and the most downloaded European model Mistral did not make |
| Translation as the job, not a feature | salamandraTA-7b-instruct | Apache 2.0 | 40 languages plus three regional varieties, trained on MareNostrum 5 in Barcelona |
| Content moderation and safety | Shieldstral 1.0 3B | Apache 2.0 | New in August. 88.1% F1 on WildGuardTest, 97.7% on multimodal content, and it moderates images as well as text |
| Maximum capability, under $20m a month | Mistral Medium 3.5 | Modified MIT, revenue-capped | 77.6% on SWE-Bench Verified, but the rights vanish the month your company goes over the cap |
| Nothing, skip it | Teuken-7B v0.6 | CC-BY-NC-4.0 | Non-commercial only. German public money, and you cannot put it in a product |
The Licence Trap That Will Cost You
Two definitions, because “open” is carrying a lot of unearned weight in AI marketing. Open weights means you can download the parameters. Open source means you can also use them commercially without asking, under a licence an ordinary lawyer recognises. Several models sold as European sovereign AI are the first and not the second.
Meta’s Llama 4 Acceptable Use Policy ends with this: “the rights granted under Section 1(a) of the Llama 4 Community License Agreement are not being granted to you if you are an individual domiciled in, or a company with a principal place of business in, the European Union.” A European company cannot license Llama 4’s multimodal models. An American one can, then sell the result back to European users.
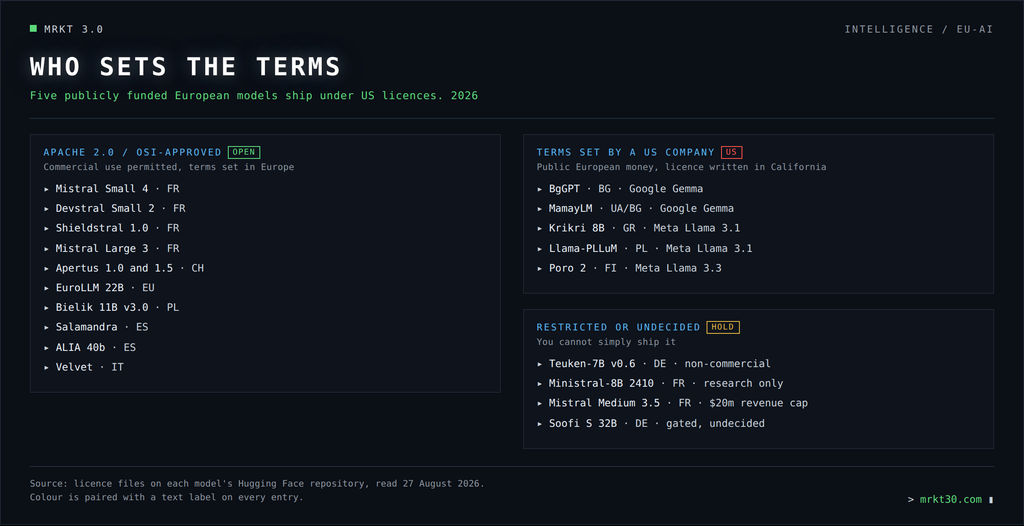
That is not an American problem alone. Bulgaria’s BgGPT and Ukraine’s MamayLM ship under Google’s Gemma terms. Greece’s Krikri and Poland’s Llama-PLLuM ship under Meta’s Llama 3.1 licence, Finland’s Poro 2 under Llama 3.3. All five are built by public research institutions, funded by ministries or EU programmes, and marketed as sovereign capability. Their terms are set in Mountain View and Menlo Park.
And the trap that catches people who did read the licence: Ministral-8B-Instruct-2410 is not open source, because it ships under the Mistral Research License. Ministral-3-3B-Instruct-2512, from the same company, is Apache 2.0. The names are almost identical, the terms are opposites, and both pulled about 360,000 downloads last month. Check the licence file on the exact repository you are pulling, never the family.
The Model That Will Not Run in Your Tool
Apertus v1.5 is the most interesting European release of the summer: image and audio input, an optional thinking mode, a 262,144-token context window, and published training data almost nobody else offers. It is also the one place in this list where the specification and the reality come apart.
Apertus 1.5 is multimodal, and llama.cpp, Ollama and LM Studio cannot load that architecture. To run it locally you have to use a community repackaging with the vision and audio stripped out, which deletes the reason to upgrade. There is exactly one such build of the 8B, made by one person, and only at Q8_0. The official Apertus documentation for Ollama still tells you to install the September 2025 model.
Pick Apertus for the licence and the training-data transparency, which are real and rare. Do not pick it expecting the 1.5 features to work in the tool you already have open.
Why the Best Model Is Never the Most Used
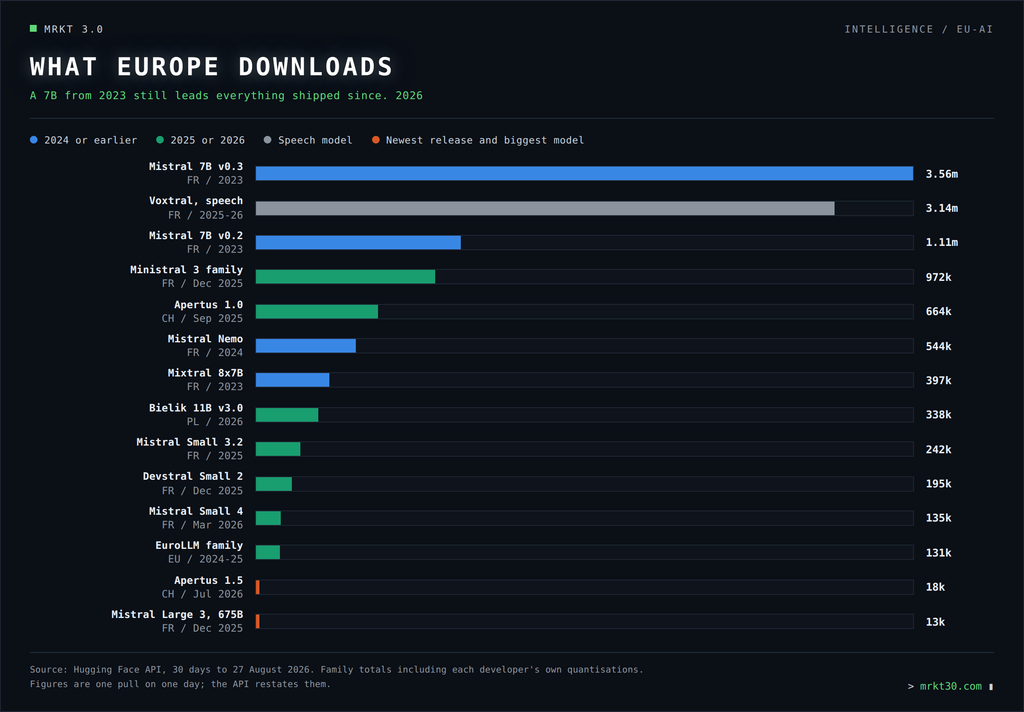
One number explains more about this market than any benchmark. Europe’s largest open model, Mistral Large 3 at 675 billion parameters, pulled 12,756 downloads last month. A 7B from 2023 that Mistral superseded years ago pulled 3.5 million. That is 279 to one, and it is a hardware judgement rather than a quality one.
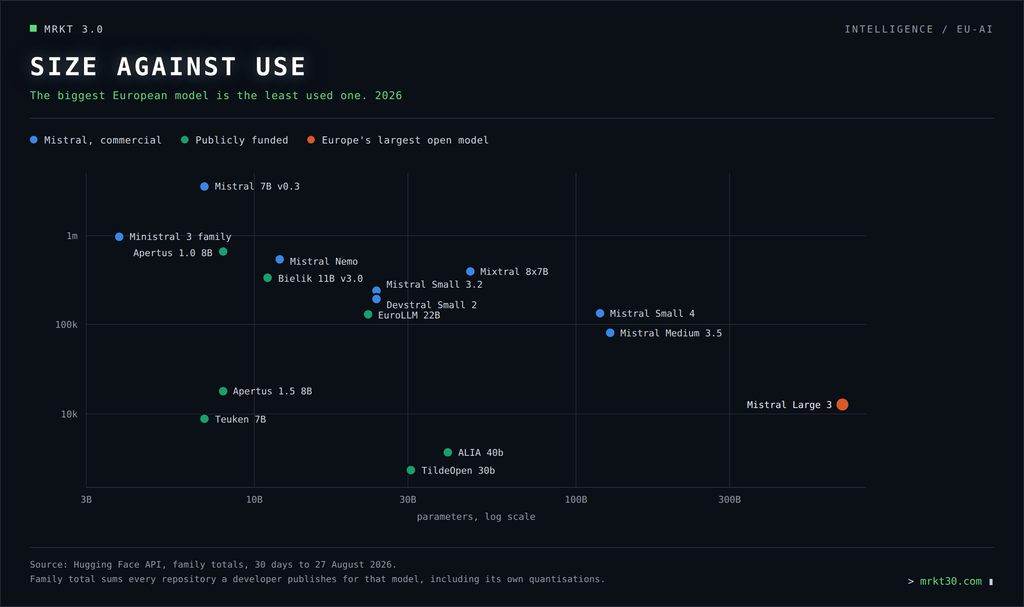
There is a better signal buried in the same data. Of those 12,756 Mistral Large 3 downloads, 89% were an Nvidia NVFP4 quantisation rather than the original weights. Bielik’s AWQ build outdraws its own base release two to one. Krikri’s GGUF outdraws its instruct model. Nobody quantises a model they are not putting into production, so the quantisation counts are the closest thing here to a deployment number. If you want to know what European companies actually run, look at which builds they shrink.
Every European model, who funds it and how long that funding runs, is in our European LLM map.
How to Pick, in Three Steps
- Start with the licence, not the benchmark. Decide what your organisation can sign. That removes more options than any capability score will, and it removes them permanently.
- Then check what fits on the hardware you own. The 279-to-one gap above is the whole market telling you that this, not quality, is what decides adoption.
- Only then look at scores. And check the exact repository, not the model family, before you deploy anything.
Europe has no model near the top of the open-weight field, and that position is held by four Chinese labs by a margin that grew this month. What Europe has is licences you can sign, training data you can inspect, and models sized for hardware that exists in ordinary companies. For most European businesses that is worth more than thirty points of index score.
We test these models one at a time and publish what we find. Apertus 1.5 is next.
Frequently Asked Questions
On capability, Moonshot’s Kimi K3, which scores 60 on the Artificial Analysis v4.1.1 index against 58 for Alibaba’s Qwen3.8 and 57 for Z.ai’s GLM-5.3-Flash. On licence quality and European hosting, Mistral Small 4 under Apache 2.0. The two answers are different because the top of the field is Chinese and the best permissive terms are not.
Devstral Small 2 24B for code and Apertus v1.5-8B for general use, both Apache 2.0 and both able to run on a single well-specified machine. One warning on Apertus: its multimodal features do not work in Ollama or LM Studio, because those tools cannot load the architecture and the community builds strip the vision and audio out.
Under OSI-approved licences with commercial use permitted: Mistral Large 3, Mistral Small 4, Devstral Small 2, Shieldstral, Apertus, EuroLLM, Bielik, ALIA, Salamandra and Velvet. Not open source despite the framing: Teuken-7B v0.6 and Ministral-8B are non-commercial, BgGPT and MamayLM ship under Google’s Gemma terms, Krikri and Poro 2 under Meta’s Llama licences, and Mistral Medium 3.5 withdraws its rights grant above $20m monthly revenue.
Only if you have data-centre hardware. It is 675 billion parameters with 41 billion active under Apache 2.0, and its family pulled 12,756 downloads last month against 3.5 million for a 7B from 2023. Of those, 89% were an Nvidia NVFP4 quantisation rather than the original weights, which tells you how few people can load it as released.
Author: Akos Szima
This article is for information only and is not financial advice. First published 10 August 2026 and rewritten 27 August 2026. Download figures are family totals from the Hugging Face API pulled on 27 August 2026; they are one pull on one day and the API restates them, so read them as orders of magnitude. Index scores are Artificial Analysis v4.1.1, checked the same day. Full table and method in the European LLM map.
See Also:
European LLMs in 2026: The Complete Map
Chinese LLMs in 2026: The Complete Map