
OpenEuroLLM is a €37.4 million project, part-funded by the EU, in which 20 universities, research bodies, companies and supercomputing centres are building open-source AI models for every official EU language. Its first model, the 9.1 billion-parameter Prelude, has been public only as unfinished checkpoints since the summer, and the deadline for its first finished models is December 31.
At a glance
OpenEuroLLM
EU-funded project to build open-source large language models for all EU languages, February 2025 to January 2028
- Led by
- Jan Hajič, Charles University, Prague; co-led by AMD Silo AI, Finland
- First model
- Prelude, a base model under Apache 2.0, still in training on the Leonardo supercomputer
- Languages
- 36 targeted; ~80% of training data is English + code + math
- Computing
- More than 10m GPU hours on four EuroHPC supercomputers, granted in December 2025
- Deadlines
- First models December 31, 2026; final models January 31, 2028
- Online
- openeurollm.eu; models on Hugging Face as openeurollm
What Is OpenEuroLLM?
OpenEuroLLM is an EU-backed project to build a family of open-source large language models for every official EU language and more. It started on February 1, 2025, runs until January 31, 2028, and receives part of its funding from the Digital Europe Programme. The Commission also awarded it the STEP seal for strategic technology projects.
Open here means more than free weights. The project promises to publish its data, documentation, training and testing code, and evaluation metrics. It already posts checkpoints, training logs and its task board in public.
It is not building a chatbot. “The intent here isn’t to build a chatbot or an AI assistant,” Peter Sarlin of AMD Silo AI said in February 2025. The models are meant as foundations that companies and public bodies can adapt for their own uses.
Who Is Behind OpenEuroLLM?
Twenty organisations in nine countries, coordinated by Jan Hajič of Charles University in Prague and co-led by AMD Silo AI, the Finnish lab that AMD bought in 2024. AMD listed the members when work began.
| Type | Members |
|---|---|
| Universities and research (11) | Charles University (coordinator), University of Helsinki, University of Turku, University of Oslo, Eindhoven University of Technology, University of Tübingen, ELLIS Institute Tübingen, Fraunhofer IAIS, Forschungszentrum Jülich, AI Sweden, ALT-EDIC |
| Companies (5) | AMD Silo AI (co-lead), Aleph Alpha Research, LightOn, ellamind, Prompsit |
| Supercomputing centres (4) | CINECA (Italy), CSC (Finland), Barcelona Supercomputing Center, SURF (Netherlands) |
AMD Silo AI is the only member with a non-European owner. Finland’s government later assured the Commission that nothing would leak from Silo AI’s Finnish arm.
Mistral, Europe’s best-known model maker, is not a member. “I tried to approach them, but it hasn’t resulted in a focused discussion about their participation,” Hajič said in February 2025.
How Much Does OpenEuroLLM Cost?
The total budget is €37.4 million, of which €20.6 million comes from the Digital Europe Programme, according to the Commission. The partners cover the rest. A figure of €52 million still circulates online, but no official source for it appears in Commission or project documents.
Computing time comes on top, through EuroHPC, the EU’s supercomputing body. The project won 1.5 million GPU hours on Finland’s LUMI in May 2025. In December it gained strategic access to more than 10 million GPU hours on LUMI, Leonardo, JUPITER and MareNostrum 5.
That is small next to private labs. Mistral raised €3 billion in September alone, at a valuation of more than €21 billion. “We know what it takes to build models, it’s not something you need billions for,” Sarlin said in February 2025.
What Is Prelude?
Prelude is OpenEuroLLM’s first model, a 9.1-billion-parameter base model built like Alibaba’s Qwen3 and released under the Apache 2.0 licence. It is training on 1,024 GPUs on the Leonardo supercomputer in Italy and is planned to see about 10 trillion tokens, according to the project’s Prelude page.
It is not finished. The page still marks it “Pretrained (awaiting alignment)” and warns that the checkpoints are “not instruction-tuned or safety-aligned yet.” On October 27 the team wrote that it would evaluate the remaining checkpoints “once annealing is finished”, the last phase of pretraining.
People are already trying it. Prelude was downloaded 7,964 times on Hugging Face in the 30 days to November 11, by our check. The base versions of EuroLLM-9B and Switzerland’s Apertus-8B had 2,170 and 9,099, though their chat versions are downloaded far more.
Which Languages Does Prelude Speak?
Prelude targets 36 languages, covering every official and co-official EU language plus neighbours such as Norwegian, Icelandic, Turkish, Ukrainian and Georgian. About three-quarters of its training data is still English (roughly 80% once code and math are included), the project’s data repository shows.
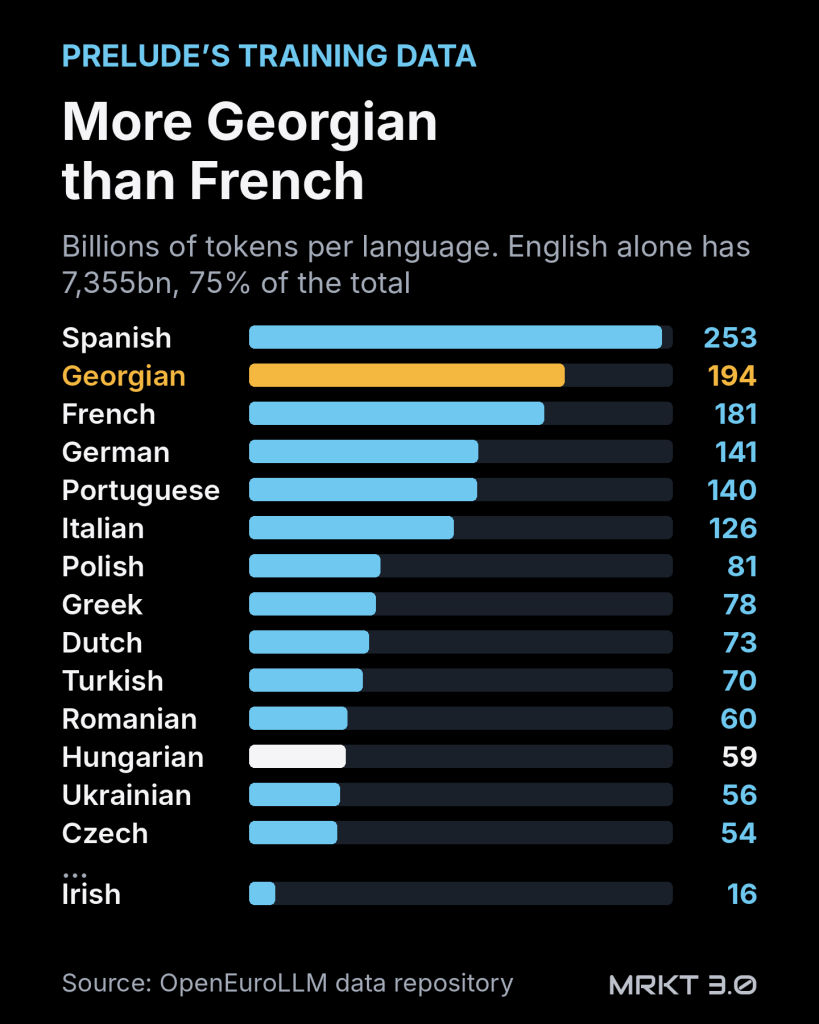
Georgian, which is not an EU language, gets 194 billion tokens, more than French (181 billion) or German (141 billion). Hungarian gets 59 billion and Irish 16 billion, while Latgalian, a regional language of Latvia, gets none. We found no explanation from the project for the Georgian share.
How Good Is Prelude?
Nobody can say yet, because the team has published no official scores. The only Prelude benchmark figures we found are the team’s own English tests at 3trn tokens, under a third of the way through training. Prelude scored 55.9% on MMLU, a general-knowledge test, and 26.4% on GSM8K, a school-maths test.
Those are early base-model results, so they say little about the finished model or about languages other than English. The fairest comparison will be with other open European models of a similar size, such as EuroLLM-9B and Apertus.
Is OpenEuroLLM Behind Schedule?
Its base models arrived roughly on time, but only as unfinished checkpoints. In May 2025 Hajič said in an interview that “naše základní modely budou nejpozději v polovině roku 2026” (“our base models will be out by mid-2026 at the latest”).
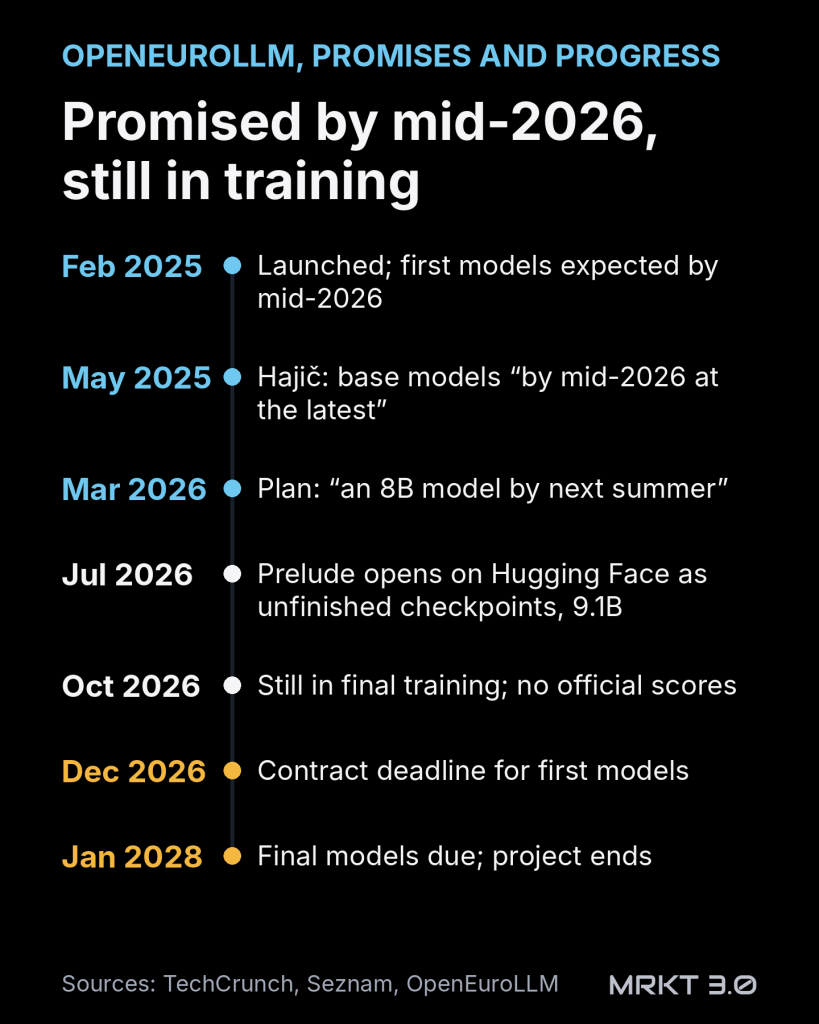
In March 2026 the plan was to “release an 8B model by next summer.” What appeared from July was a 9.1 billion-parameter model in unfinished checkpoints. The project’s list of deliverables still gives December 31, 2026 for the first models and January 31, 2028 for the final ones.
Hajič has been frank about Europe’s position from the start. “Je to pozdě, to tam klidně napište” (“It’s late, you can write that down”), he said in February 2025 of Europe’s entry into the AI race. In the project’s first-year update in March, he said that “significant challenges, especially in securing more compute for creating the final models, still remain.”
A bigger model is under way. “A 32B dense model is in its opening bars,” the Prelude page still says.
How Does OpenEuroLLM Compare With EuroLLM, Mistral and EUROPA?
It is one of several European efforts, and the EU is now backing a much larger one. Our map of European LLMs tracks them all.
| Project | Who builds it | Size | Status, November 2026 |
|---|---|---|---|
| OpenEuroLLM Prelude | 20-member EU consortium | 9.1B | In training; checkpoints public |
| EuroLLM | Unbabel-led consortium | 9B and 22B | 9B released December 2024; 22B in 2026 |
| Apertus | Swiss AI Initiative | 8B and 70B | Released September 2025; version 1.5 in July 2026 |
| EUROPA | Domyn-led consortium | 400B+ planned | Picked by the Commission in June 2026 |
EuroLLM trained its 9B model on 4trn tokens in 35 languages and released it in December 2024. The two projects now share work on synthetic training data.
In June the Commission chose a consortium led by Italy’s Domyn to build EUROPA, an open model of more than 400 billion parameters in all 24 EU languages.
Mistral works alone and has moved faster. It released the weights of Mistral Large 4 in late October.
Can You Use OpenEuroLLM Today?
The checkpoints are free to download under Apache 2.0, which allows commercial use. Prelude is a base model, though, so it continues text instead of following instructions. Its card calls it a research artifact for studying how models train and warns against production use.
The team has also posted an experimental instruction-tuned version, oellm-9b-256k-sft. It answers prompts but is not a finished product either.
Anyone who needs a working open model in European languages today has better options. Our guide to the best open-source LLMs compares them.
Author: Akos Szima
See Also:
European LLMs in 2026: The Complete Map
Is Mistral Large 4 the Best Open Model Outside China?
Who Owns Mistral AI? What the Company’s Own Filings Show
How We Checked This:
We read the Commission’s announcement, the project’s website, deliverables list, blog and Prelude page, its Hugging Face cards, its training-data repository and its public evaluation notes on GitHub. Download counts come from the Hugging Face API on November 11. Token counts are from the data repository, which warns that some of its documents are not fully up to date. The member list is AMD’s from the launch; the project’s site now names 21 partners. Czech quotes are from Lupa.cz and Seznam Zprávy, translated by us. Download the data, with sources (CSV).
Change log: November 12, 2026, first published.
Frequently Asked Questions:
The EU’s Digital Europe Programme pays €20.6 million of its €37.4 million budget, and the 20 partners cover the rest. Computing time comes separately through EuroHPC, which granted it more than 10 million GPU hours in December 2025.
Yes. Its first model, Prelude, is released under the Apache 2.0 licence, and the project publishes its training data sources, code, logs and evaluation notes.
Its first models are due by December 31, 2026 under the grant, and its final models by January 31, 2028. Unfinished checkpoints of Prelude have been on Hugging Face since summer 2026.
This article is based on EU documents, the project’s own pages, Hugging Face and GitHub data and published interviews. MRKT 3.0 has no commercial relationship with OpenEuroLLM or its partners.